
Unlimited Google Scholar scraper for AI agents.
A Google Scholar scraper for search results, cited-by lists, author profiles, versions and case law. Unlimited requests for one flat bill from $50/mo, no credits, and a blocked request is free.
No card. Unlimited pages. 5 threads. Failed requests $0
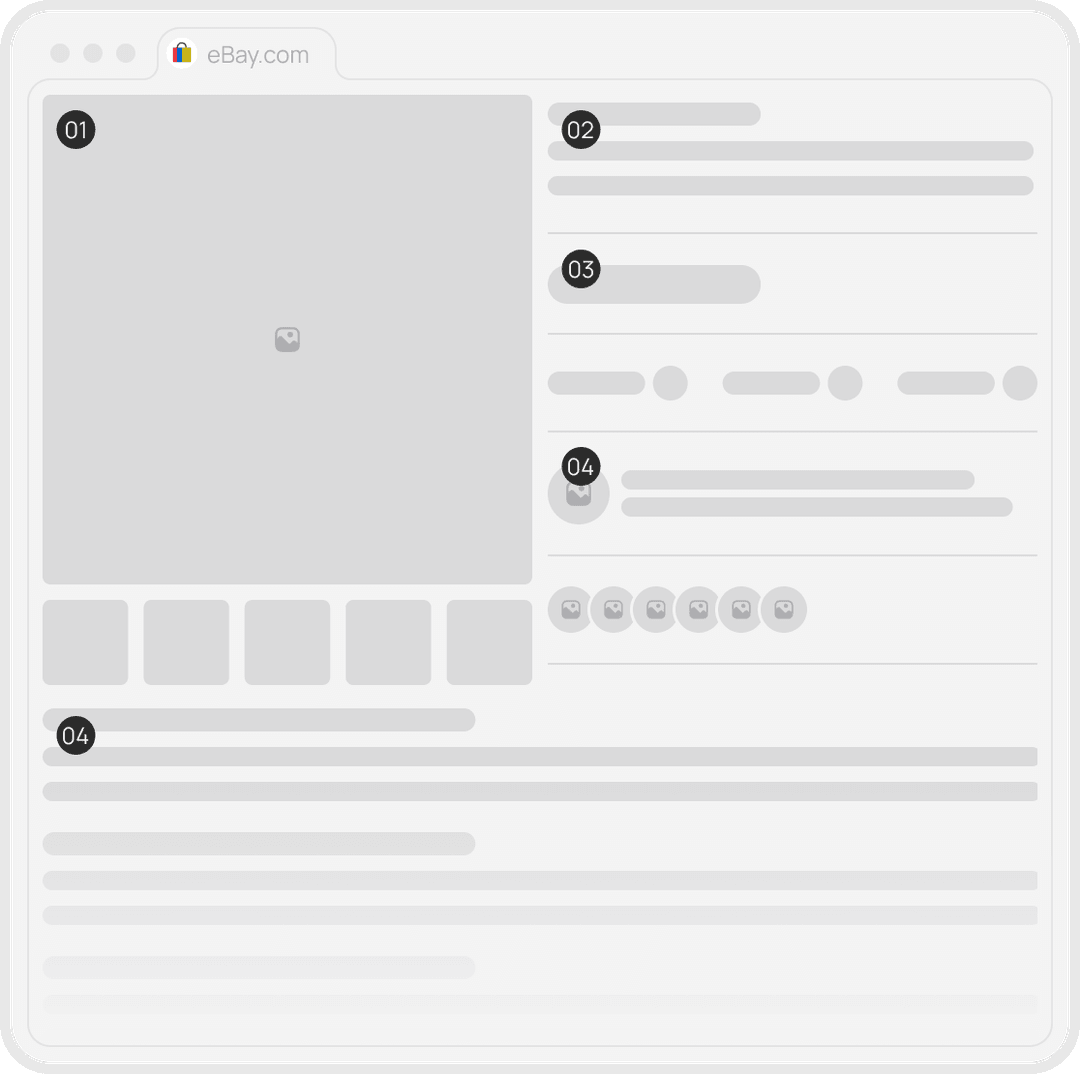
Images
Title
- Title
- Condition
Price & bidding
- Price
- Bids
- Time left
- Watchers
Seller
- Seller rating
- Sold listings
Specifics & shipping
- Item specifics
- Shipping
- Item location
JavaScript rendered, parsed to JSON or Markdown, and a fetch that fails after three retries is never billed
Call it on Google Scholar
curl -X POST "https://scraper.geonode.io/v1/extract" \
  -H "X-Api-Key: $GEONODE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "url": "https://scholar.google.com/scholar?q=attention+is+all+you+need&hl=en",
  "formats": [
    "json",
    "markdown"
  ],
  "render_js": true,
  "proxy": {
    "country": "US"
  }
}'
You came for an Google Scholar scraper. The key opens everything.
100% first-pass success
you’re here
Result entry: Title, Authors, Venue, Year, Snippet, Result ID, Document type tag
Result links: Cited by count, Cited by URL, Related articles URL, All versions count, PDF link, Publisher link
Search controls: Query, Year range, Sort by date flag, Include citations flag, Language, Start offset
Author profile: Author name, Affiliation, Verified email domain, Interests, Total citations, h-index, i10-index
Profile publications: Publication title, Co-authors, Journal, Year, Citations per paper, Citations per year chart
One subscription, from $50 a month flat. Everything after the first line adds $0
The hard part is getting in. That's our part.
$50/moflat, priced by concurrency, not per request
0credits, meters or per-page charges
$0for any Google Scholar request that still fails after 3 retries
48 hfree trial on your own Google Scholar URLs
Cloudflare98%
Akamai97%
Imperva Incapsula97%
DataDome96%
PerimeterX / HUMAN95%
reCAPTCHA v395%
Kasada94%
hCaptcha93%
First-pass success by anti-bot vendor, measured by us over 30 days, so of course it flatters us. The 48-hour trial exists so you can count against your own URLs. Full benchmark
What unlimited changes for Google Scholar data
Sold-comps pricing
Completed listings are the real price of anything. Pull them at scale and price with evidence.
Arbitrage sourcing
Sweep categories for mispriced inventory continuously instead of when the credit budget allows
Demand research
Bids, watchers and sell-through, across a whole category, on one flat bill
Collection tracking
Every listing of the thing you care about, the moment it appears
Cheap is supposed to be the trade-off
- Michael T.
Switched from Bright Data. Same quality, fraction of the cost. Their wholesale model actually makes sense.
- Kristina Halvorson
Finally a proxy provider that actually feels built for developers
- Edgar Weissnat
We run multiple large-scale data collection pipelines across several regions, and proxy reliability has always been one of the biggest bottlenecks. After switching to Geonode we noticed two immediate improvements: connection stability and predictable pricing. Previously we had to constantly optimize traffic to avoid massive proxy bills. With Geonode’s wholesale pricing model we can focus on building products instead of worrying about proxy usage. Integration with our Python stack and Playwright automation was straightforward and took less than a day.
- Gladys Paucek
Best proxy infrastructure I've used. The MCP integration with our AI agents was seamless.
- Gladys Paucek
Finally something that doesn’t feel like enterprise sales software.
Pick your thread count. That's the only decision.
Nothing is metered. Plans price threads (how many requests run at once), and pages stay unlimited on every one. An Google Scholar page that needs an anti-bot bypass costs exactly what a plain page costs
Roughly what each plan clears in a month, by endpoint
Starter
2 threads
$50 /mo
Growth
5 threads
$100 /mo
PopularScale
25 threads
$400 /mo
Pro
100 threads
$1,250 /mo
Max
250 threads
$2,500 /mo
The 48-hour trial runs at five threads, no card. Custom terms past 250 threads.
Yeah, but...

48 hours. Your worst Google Scholar URLs.
Five threads, no card, and the clock starts at your first API call. If it doesn’t earn the switch, don’t switch.


